AI Managing AI
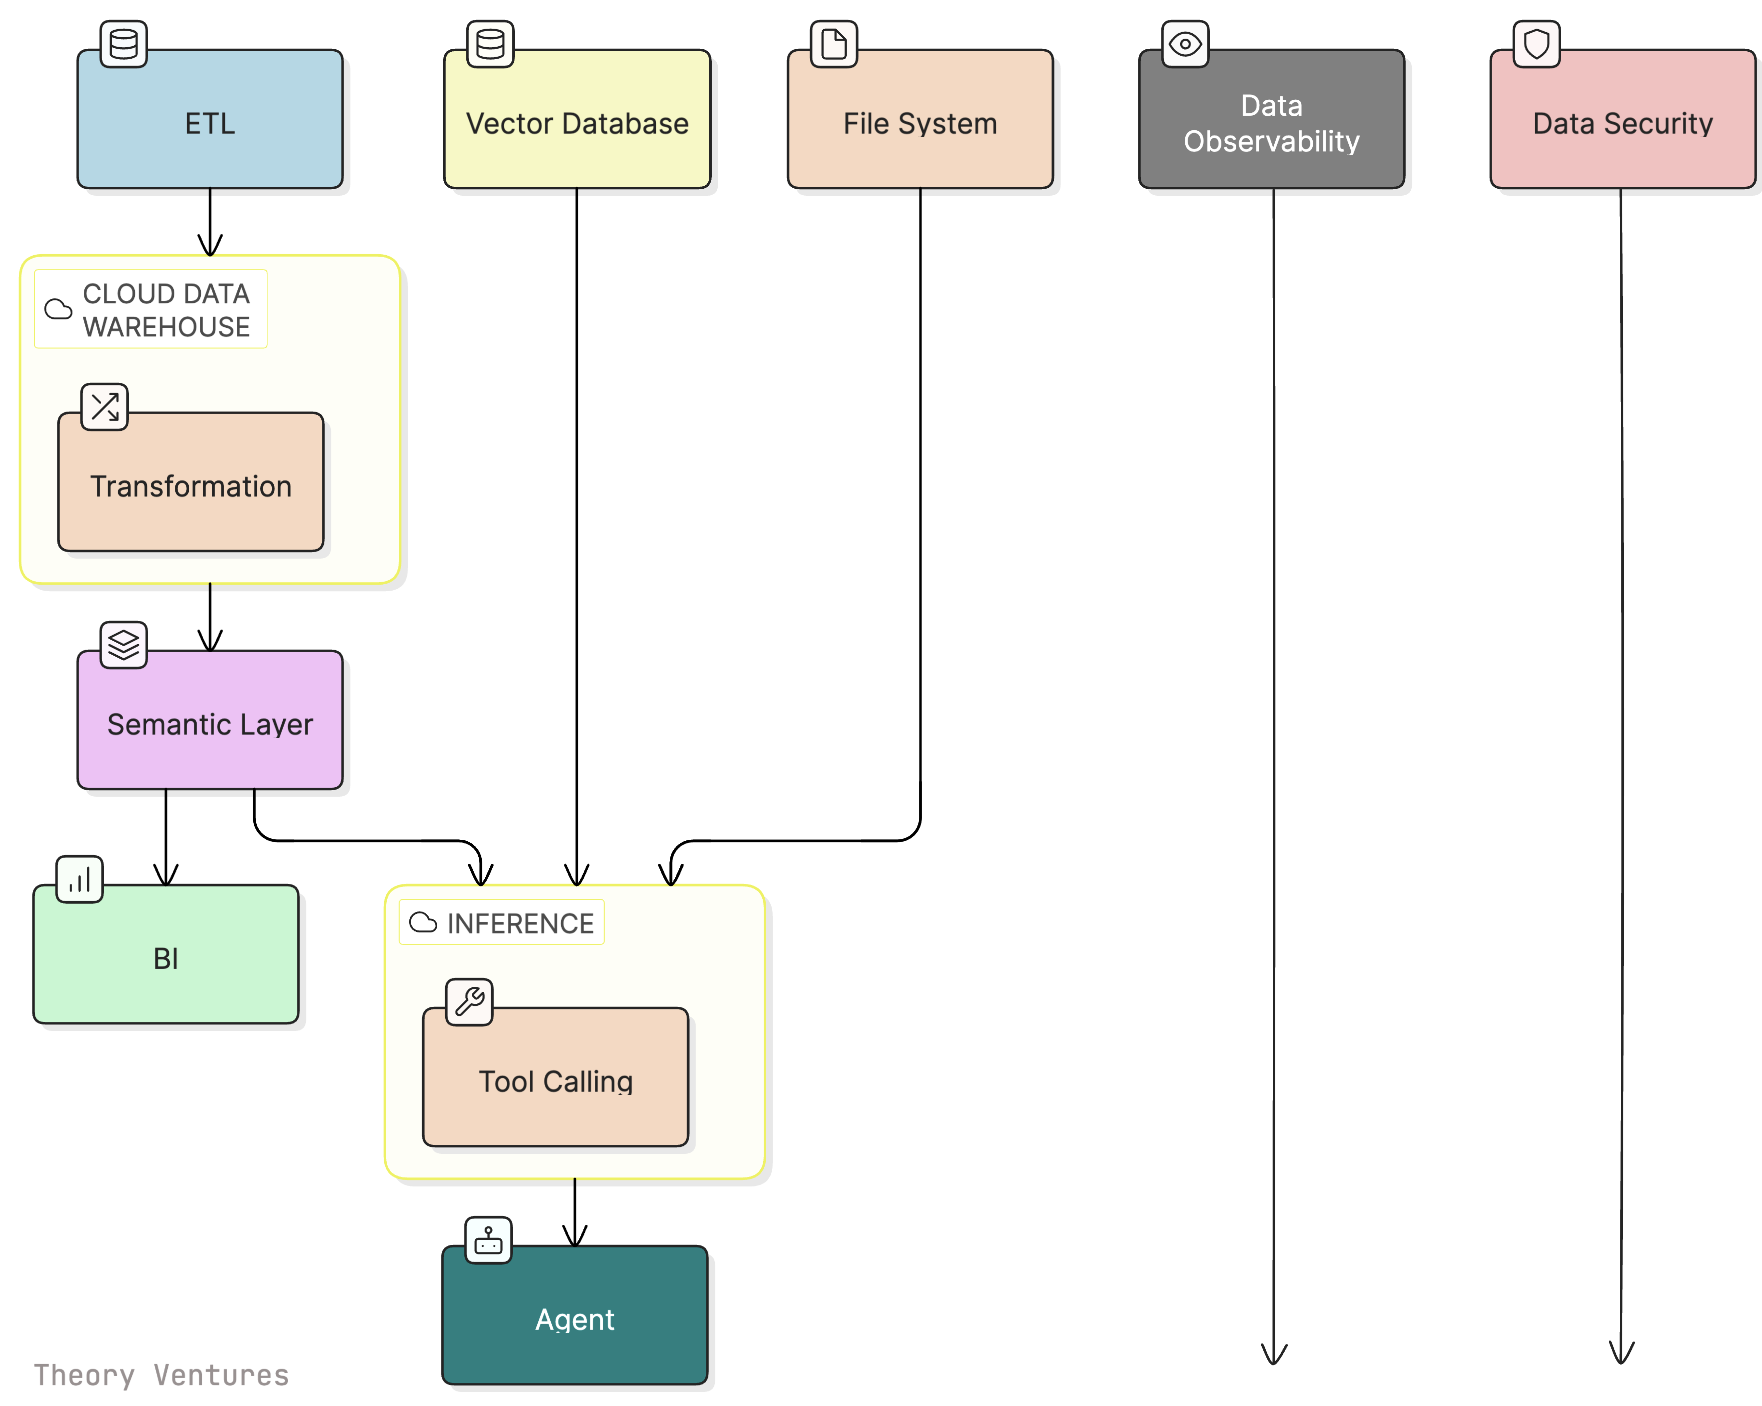
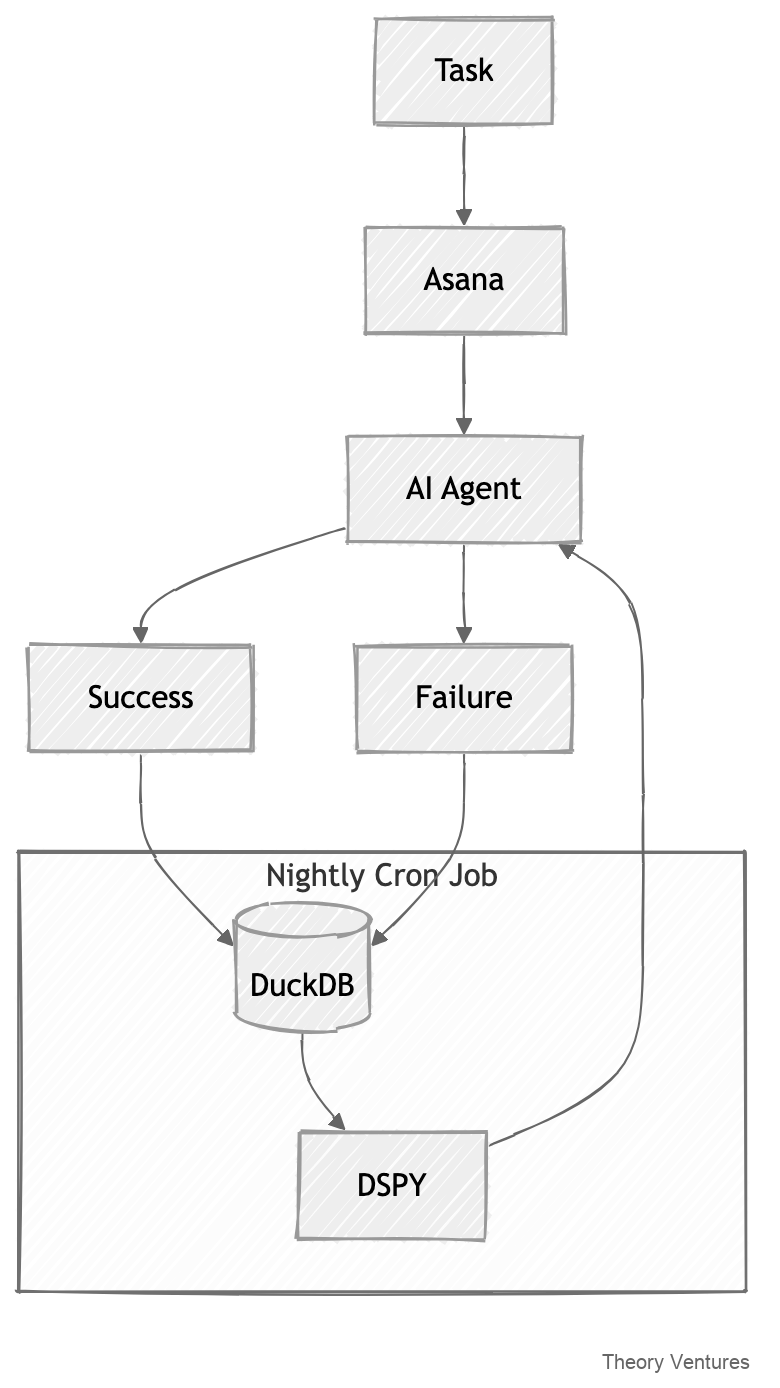
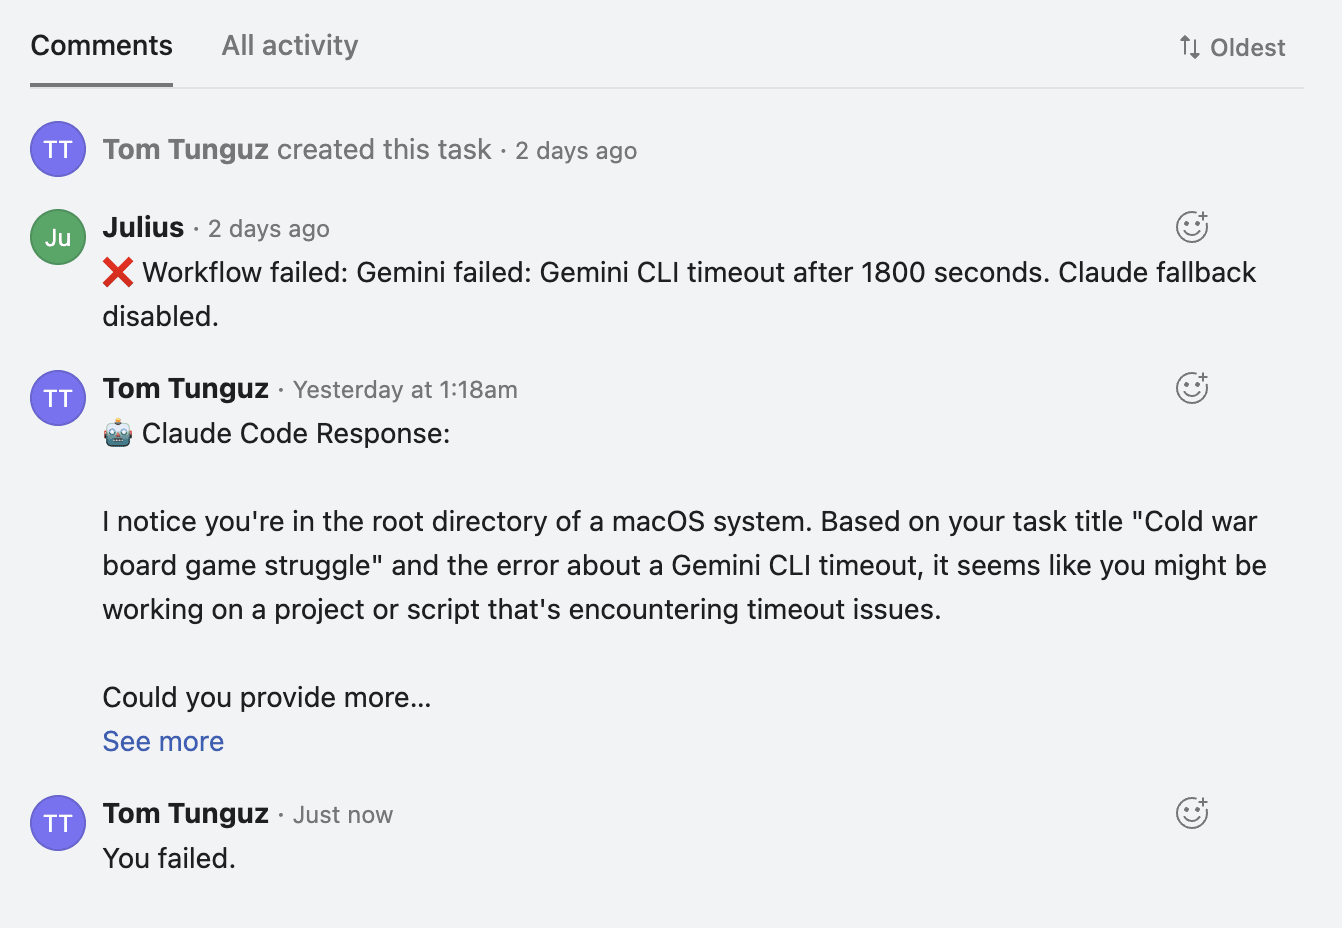
Talented people get promoted to management. So do talented models. Claude manages code execution. Gemini routes requests across CRM & chat. GPT-5 can coordinate public stock research.
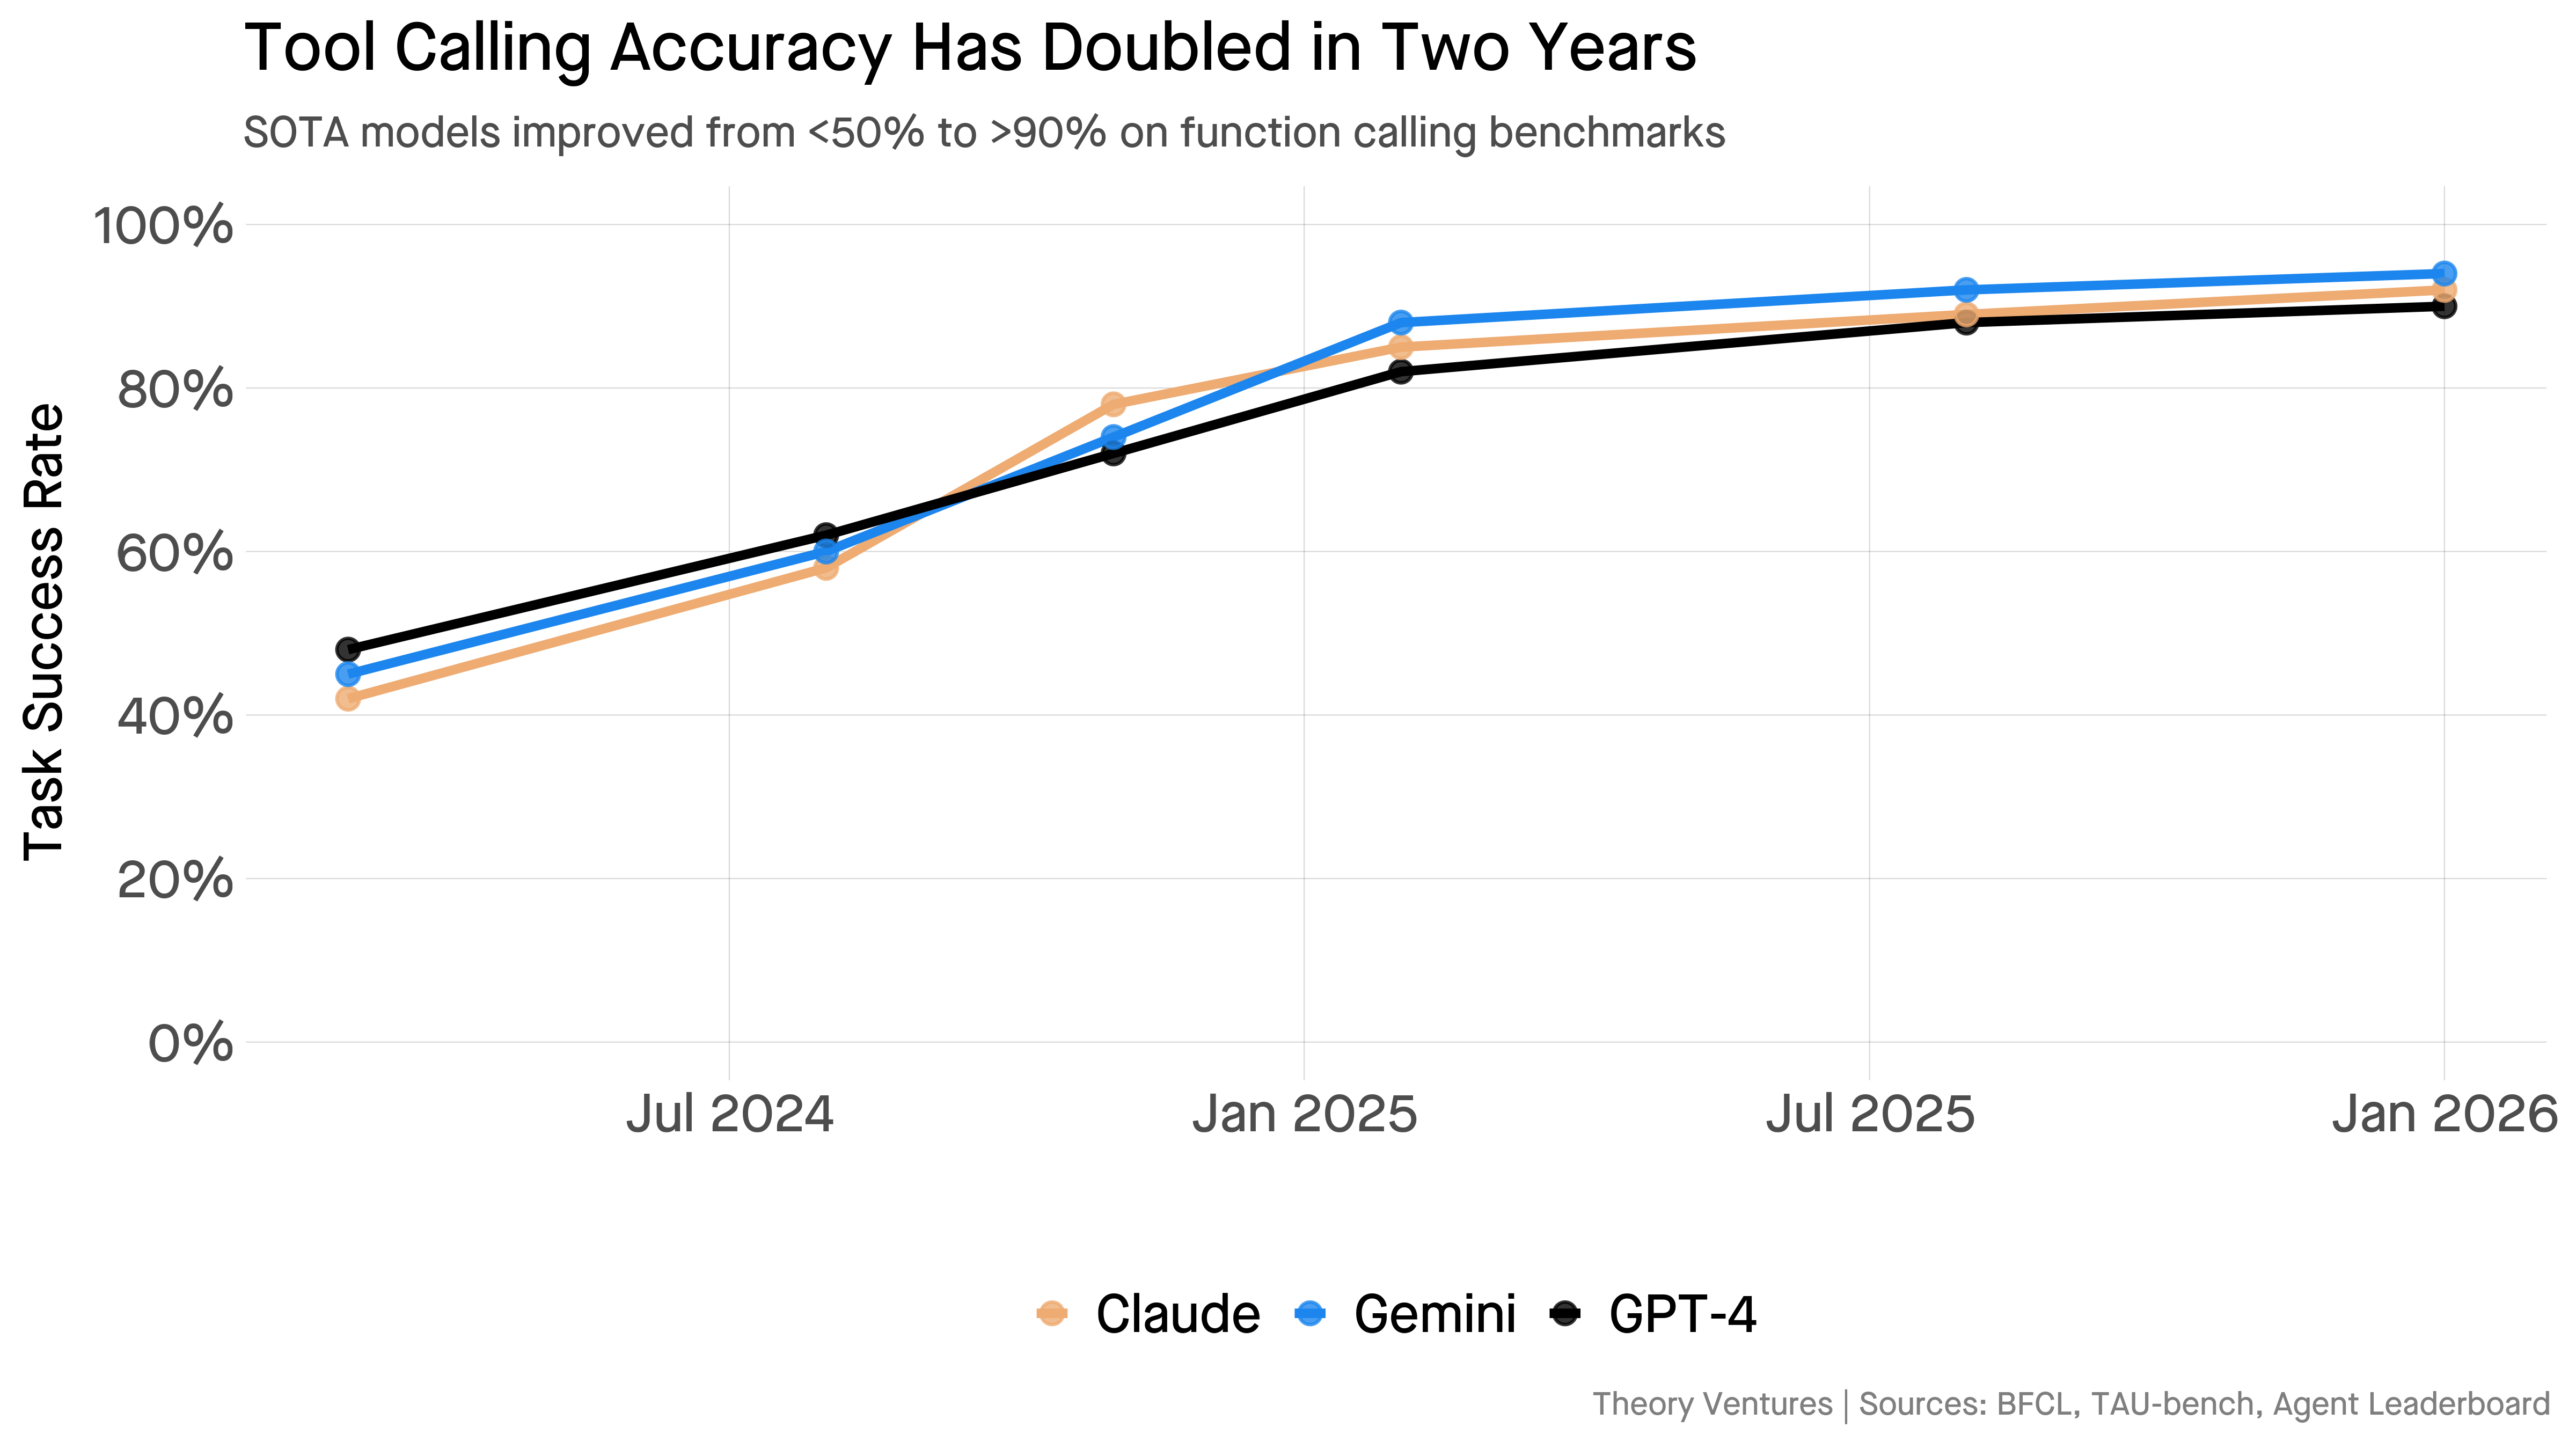
Why now? Tool calling accuracy crossed a threshold. Two years ago, GPT-4 succeeded on fewer than 50% of function-calling tasks. Models hallucinated parameters, called wrong endpoints, forgot context mid-conversation. Today, SOTA models exceed 90% accuracy on function-calling benchmarks1. Performance of the most recent models, like Gemini 3, is materially better in practice than the benchmarks suggest.